Repository: https://github.com/isaac-for-healthcare/i4h-workflows
End-to-end workflows from simulation to real-world deployment
Isaac for Healthcare - Workflows#
IsaacLab-Arena simulation for healthcare robotics, with one workflow-based runtime for task execution, data collection, and policy evaluation.
A Scene describes the simulated world. A Workflow connects that Scene to the Tasks needed for a healthcare robotics procedure. The Engine runs those Tasks in the simulator.
Available Workflows#
Agent-ready Workflows#
The workflow repository supports agent-assisted setup, execution, authoring, and validation through natural-language prompts. These workflows can run with supported coding agents or with the repository's locally hosted agent stack.
For local inference, the Local i4h Agent runs NVIDIA Nemotron with SGLang and OpenCode, keeping workflow execution on your own NVIDIA GPU or DGX Spark. See Use with an AI Agent for agent-ready examples and instructions.
Layout#
The repository has seven main components:
common/— shared data contracts and recording formatsarena/— Isaac Sim scenes and runtimetasks/— reusable robot behaviors and policy integrationsrl/— reinforcement learning profilesworkflows/— workflow definitions organized in the workflow layout and specialty catalogengine/— task graph execution and workflow validationtools/— dataset processing and visualization tools
See DESIGN.md for detailed architecture and ownership rules.
Requirements#
- Ubuntu 22.04 or 24.04 on
x86_64oraarch64 - RTX-capable NVIDIA GPU with 16 GB VRAM minimum for Isaac Sim; 48 GB recommended for i4h workflows
- Linux driver
580.95.05(the Isaac Sim 6.0 tested version) or a compatible newer production-branch driver - Some training profiles require more VRAM or multiple GPUs; see the workflow-specific documentation
uvandgit- CUDA Toolkit 12.x or 13.x, no newer than the driver supports, for endoluminal RL (CUDA fluoroscopy by default),
--fluoro-device cuda, or the standalonexray-simulatorCLI; see TROUBLESHOOTING.md - Network access for Python packages, third-party checkouts, models, and assets
- Tens of GB for dependencies, plus additional model-cache space (large checkpoints such as GR00T N1.7 can require several dozen GB)
- Optional for natural-language prompts: Claude Code, Codex, or the repository's Local Agent. Tested with Opus 4.8 (1M context) and GPT-5.5 at low or medium reasoning effort.
Supported Workflows#
Workflows are organized by clinical robotics specialty. The specialty affects source layout only; workflow IDs and run.sh commands remain unchanged.
✓ means available, — means unavailable, and “RL training required” means you must train and export a policy first.
Laparoscopic Robotics#
| Preview | Workflow | Purpose | Robot | Policy readiness | Rule-based |
|---|---|---|---|---|---|
 |
surgical_lift_block |
Grasp and lift a peg-transfer block. | dVRK PSM | — | ✓ |
 |
surgical_lift_needle |
Grasp and lift a suture needle. | dVRK PSM | — | ✓ |
 |
surgical_lift_needle_organs |
Lift a suture needle from an organ bed. | dVRK PSM | — | ✓ |
 |
surgical_reach_dual_psm |
Reach two targets with two arms. | dual dVRK PSM | — | ✓ |
 |
surgical_reach_psm |
Reach a target with one PSM arm. | dVRK PSM | — | ✓ |
 |
surgical_reach_star |
Reach a target with a STAR arm. | STAR | — | ✓ |
Ultrasound Robotics#
| Preview | Workflow | Purpose | Robot | Policy readiness | Rule-based |
|---|---|---|---|---|---|
 |
ultrasound_liver_scan |
Sweep an ultrasound probe across an abdominal phantom. | Franka-style arm | ✓ openpi PI0 | ✓ |
|
ultrasound_probe_reach |
Align a probe with a randomized target. | Franka-style arm | RL training required | — |
Endoluminal Robotics#
| Preview | Workflow | Purpose | Robot | Policy readiness | Rule-based |
|---|---|---|---|---|---|
 |
endoluminal_navigation |
Navigate a catheter with live fluoroscopy in demo mode. |
XPBD catheter + orbital C-arm | — | — |
|
endoluminal_navigation_arm |
Navigate a catheter carried on a Franka Panda flange with live fluoroscopy. | Franka Panda + XPBD catheter + orbital C-arm | GR00T N1.7 training required | — |
Hospital Automation Robotics#
| Preview | Workflow | Purpose | Robot | Policy readiness | Rule-based |
|---|---|---|---|---|---|
 |
assemble_trocar |
Assemble and place a trocar. | Unitree G1 + dex hands | ✓ GR00T N1.5 | — |
 |
locomanip_push_cart |
Walk to and push a cart. | Unitree G1 | ✓ GR00T N1.6 | — |
 |
locomanip_tray_pick_and_place |
Move a surgical tray from a shelf to a cart. | Unitree G1 | ✓ GR00T N1.6 | — |
 |
scissor_pick_and_place |
Pick up scissors and place them in a tray. | SO-ARM 101 | ✓ GR00T N1.5 / N1.7 | ✓ |
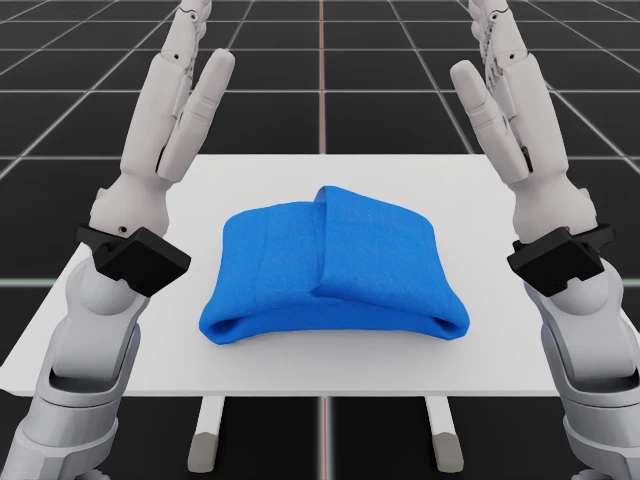 |
spread_tablecloth_g1 |
Tablecloth spreading via XR hand tracking. | Unitree G1 + Inspire hands | — | — |
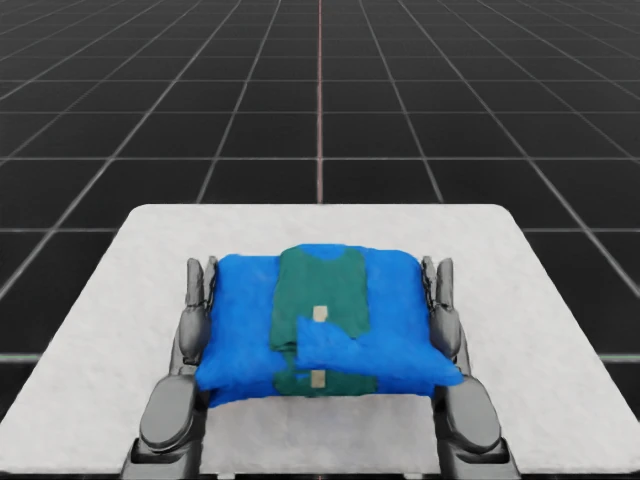 |
spread_tablecloth_h2 |
Tablecloth spreading via XR hand tracking. | Unitree H2 + Sharpa hands | — | — |
PhysX is the default physics backend except for the tablecloth workflows, which use coupled Newton cloth physics. The laparoscopic workflows also support Newton physics. assemble_trocar also provides an RLinf PPO post-training profile.
Use with an AI Agent#
Use this interface with Claude Code, Codex, or the repository's Local Agent. Describe the outcome you want; the agent selects the appropriate repository skill, resolves the direct commands, performs the work, and reports validation evidence. Setup, execution, authoring, and the data-to-policy pipeline can all be requested through prompts.
Setup with an AI Agent#
What does the i4h workflow include, and where should I start?
Set up the i4h workflow on this machine and tell me if any host requirements are missing.
The agent checks host requirements, installs or repairs the repository dependencies, and reports anything that still blocks execution.
Run Workflows with an AI Agent#
Choose this path when one of the supported workflows already matches the robot, scene, and task you want to run. Give each prompt separately so follow-up requests such as replay and annotation can use recordings produced by the preceding evaluation.
Evaluate scissor pick and place in policy mode and record 2 successful episodes.
Replay the second episode.
Run annotation on all recorded episodes and summarize.

Evaluate ultrasound_liver_scan in policy mode for 1 episode.
Evaluate trocar assembly in policy mode for 1 episode.
Evaluate locomanip tray pick and place in policy mode for 1 episode.
Evaluate locomanip push cart in policy mode for 1 episode.

Run surgical_reach_psm in rule-based mode for 1 episode.
Run surgical_reach_psm in rule-based mode for 1 episode with Newton physics.
Run surgical_lift_needle in rule-based mode for 1 episode.
Author New Workflow with an AI Agent#
Start with an empty Scene, then add reusable Task behavior, define the Workflow goal, and expose the run modes you need.
create a new workflow with an empty scene
          ↓
edit the scene: add assets, robot, cameras, layout, physics
          ↓
add reusable task behavior
          ↓
define the workflow goal + success condition
          ↓
add run modes: rule-based, teleop, replay, policy
          ↓
validate each enabled mode
A Scene owns the simulated world. A Task owns one reusable behavior. A Workflow selects the Scene and Tasks, exposes run modes, and defines the goal and success condition.
Issue the following prompts in order. Each prompt completes one ownership boundary before the next stage depends on it:
Create a blank hospital-automation-robotics workflow named my_workflow.

Edit my_workflow live.
  - Add a surgical table.
  - Add scissors and tweezers on the table.
  - Add two destination trays named tray_a and tray_b.
  - Add a Unitree G1 robot.
  - Move G1 so its base starts 2 m from the nearest table edge.
  - Keep G1 upright and facing the center of the table.
  - Set the perspective view to frame the room, then add a room camera from that view.
  - Visually verify that the tabletop, scissors, tweezers, and both trays are visible in at least one camera.
  - Bake all changes and stop.

Continue authoring my_workflow with a rule-based G1 reach-table Task.
  - Behavior: have G1 walk forward and stop near the surgical table.

Define the goal and success condition for my_workflow.
  - Goal: G1 reaches the surgical table.
  - Success: G1 stops upright within 0.3 m of the nearest table edge.

Add these run modes to my_workflow:
  - rule-based
  - trainable GR00T N1.6 policy
Validate the rule-based rollout and statically validate all modes.

Run and record 5 successful rule-based episodes for my_workflow.
Convert and visualize the recorded data.
Fine-tune for 200 steps with a batch size of 32. Turn off vision tuning.
Evaluate the new checkpoint.
Stop all
Author New Workflow with an RL Policy using an AI Agent#
Online RL is a separate training lifecycle. It trains a policy against a Workflow's Scene, then returns the verified checkpoint to the Workflow for normal policy validation.
create a blank Workflow
          ↓
author and validate its Scene
          ↓
define the RL objective: observations + actions + rewards + success + resets
          ↓
train from scratch or RL post-train a pretrained policy
          ↓
evaluate the policy in vectorized simulation
          ↓
export the trained checkpoint and create its reusable policy Task
          ↓
add the Task to the Workflow's policy TaskGraph
          ↓
validate the complete Workflow through the normal runner
Issue these prompts in order:
Create a blank ultrasound-robotics workflow named robotic_instrument_reach.

Edit robotic_instrument_reach live.
  - Add a table and a surgical training pad.
  - Add a Franka-style arm with a probe attached to its tool frame.
  - Add a target marker on the pad and a room camera.
  - Frame the arm, probe, pad, and target in the camera view.
  - Visually verify that the arm, probe, pad, and target are visible in the room camera.
  - Bake all changes and stop.

Add an RL training objective to robotic_instrument_reach.
  - Goal: move the probe tip to the marked point on the training pad.
  - Observe the robot joints, probe pose, and target pose.
  - Control the probe with end-effector pose actions.
  - Reward reducing tip-to-target distance, with a small penalty for abrupt actions.
  - Sample a reachable target position on the pad at reset.
  - Success: hold the probe tip within 2 cm of the target for 20 steps.
  - Use PPO and run a small vectorized smoke configuration first.
  - Dry-run the training configuration.

Train the robotic_instrument_reach policy with RL and evaluate 20 randomized episodes.
Export the verified checkpoint and create a RoboticInstrumentReach policy Task from it.
Add that Task as the policy run mode of robotic_instrument_reach.
Validate robotic_instrument_reach in policy mode and report its simulator success rate.
ultrasound_probe_reach demonstrates PPO training from scratch. assemble_trocar demonstrates RL post-training from a GR00T checkpoint. The agent resolves the appropriate profile, trainer, export, and Workflow validation path.
Use from the Command Line#
Use this interface when running, debugging, scripting, or integrating the runtime without an agent. Run commands from the repository root.
Setup from the Command Line#
./setup.sh
This is the command-line equivalent of asking an AI agent to set up the repository.
Container builds, DGX Spark, Jetson AGX Thor, Zenoh, and sibling vLLM usage are documented in the Docker guide.
Run Workflows from the Command Line#
./run.sh list
./run.sh scissor_pick_and_place --rule-based --episodes 1
./run.sh scissor_pick_and_place --policy --episodes 2
./run.sh scissor_pick_and_place --replay demos.hdf5 --episode 0
./run.sh scissor_pick_and_place --teleop keyboard --record

./run.sh assemble_trocar --policy --episodes 1
./run.sh surgical_reach_psm --rule-based --episodes 1
./run.sh surgical_reach_psm --rule-based --episodes 1 --presets newton

./stop.sh all
Pass --presets newton to run a laparoscopic workflow with Newton physics. Without this preset, the workflow uses PhysX.
A bare workflow opens its Scene in idle mode. ./run.sh --help lists episode, retry, recording, checkpoint, prompt, camera, headless, and device options.
Each workflow keeps the same per-episode step cap used by its validated workflow. Policy inference wait time does not consume simulation steps.
Each run stores its logs, metadata, and recordings under ./runs/<workflow>/<YYYYMMDD_HHMMSS>/. Bare --record writes demos.hdf5 there. Use --run-dir PATH to choose a specific run directory.
Show workflow authoring instructions
### Author New Workflow from the Command Line Create an idle-only Workflow scaffold under an approved specialty:./scripts/create_blank_environment.py my_workflow \
--specialty hospital-automation-robotics \
--validate
./run.sh my_workflow --live
arena/.venv/bin/python scripts/live_scene_edit.py add-known-asset \
  --asset surgical_table \
  --prim-path /World/envs/env_0/Table
I4H_RUN_DIR="runs/my_workflow/$(date +%Y%m%d_%H%M%S)"
mkdir -p "$I4H_RUN_DIR"

arena/.venv/bin/python scripts/live_scene_edit.py export-scene \
  --workflow my_workflow \
  --root-path /World/envs/env_0 \
  --output-path "$I4H_RUN_DIR/live_scene.json"

arena/.venv/bin/python scripts/authoring_info.py snapshot \
  my_workflow "$I4H_RUN_DIR/live_scene.json"
from i4h_engine.graph import TaskGraph, task
from i4h_engine.interface import Workflow


def rule_based() -> TaskGraph:
    return TaskGraph().flow(task("basic/example"))


WORKFLOW = Workflow(
    scene="example_scene",
    modes={
        "rule-based": rule_based,
    },
    default_mode="rule-based",
)
./run.sh list
./run.sh show my_workflow --mode rule-based
./run.sh lint my_workflow --mode rule-based
./run.sh lint --all
workflows/.venv/bin/python -m pytest \
  workflows/tests/test_my_workflow_contract.py -q
./run.sh my_workflow --rule-based --episodes 1
./train.sh rl list

./train.sh rl show ultrasound_probe_reach
./train.sh rl ultrasound_probe_reach \
  --num-envs 128 --epochs 400 --dry-run

./train.sh rl show assemble_trocar
./train.sh rl assemble_trocar \
  --model-path /absolute/path/to/gr00t-sft-checkpoint \
  --num-envs 64 --epochs 1000 --dry-run
./train.sh rl <workflow> \
  --eval --checkpoint <checkpoint-or-run> --episodes 20

./train.sh rl export <workflow> \
  --checkpoint <checkpoint-or-run> \
  --output-dir <export-directory>

./run.sh <workflow> \
  --policy --checkpoint <exported-policy> --episodes 1
Run the End-to-End Pipeline#
With an AI agent:
Run end-to-end smoke pipeline for scissor pick-and-place.
From the command line:
./scripts/e2e/run.sh --env scissor_pick_and_place --dry-run
./scripts/e2e/run.sh --env scissor_pick_and_place
The runner streams progress to the terminal and prints the exact per-run workflow.log path. It performs setup, policy recording, mimic expansion, VLM filtering, replay, LeRobot conversion, visualization, fine-tuning, and checkpoint validation. Use its --skip-* flags to omit optional stages, and --headless on a host without a display.
VLM filtering grades each episode against the workflow's annotate settings (Workflow(annotate=Annotate(...))), which name the visible success criterion, the cameras to show, and whether to judge the final state or the motion; ./run.sh show <workflow> prints them, and a workflow without them is graded on its policy task's prompt. Fine-tuning needs no Weights & Biases account: PI0 logs there only with --wandb or train.wandb: true in its task manifest, and GR00T logs to TensorBoard.
Further Documentation#
- See the troubleshooting guide for setup, policy-backend, determinism, and Docker failures.
- See the workflow layout and specialty catalog for source organization and specialty-specific documentation.
- See the run-mode guide for standard modes and workflow-specific extensions.
- See the individual links in the workflow catalog for workflow-specific setup and usage.
- Use the repository skills under
skills/for AI-agent workflows. Generic Isaac Sim scene, physics, camera, USD, rendering, and spatial-authoring work routes through the upstream skills selected byi4h-workflow-scene-edit.